
In the past two decades, the concept of the value of data has changed drastically. We have moved from a position where the value of data was measured in a half-life of seconds, to one where amassing huge amounts of it can be the difference between fighting the market, and dominating it. The delta across this spectrum though is a more recent addition.
In the early 2000’s, organizations were deeply entrenched in the delivery of data warehouse architectures. Data warehouses shifted the real-time nature of databases, to a historical record that integrated multiple systems to unearth historical structured data trends for reporting purposes. These toolsets shifted focus from the present and gave business analysts the capability to review previous experiences, analyze trends and behaviors, and learn from their results to plan for the future.
In the 2010’s the trend shifted to expand beyond structured data to include raw and unstructured data in massive quantities on distributed systems, giving way to Data Lakes. The concept was simple, with the knowledge that additional information could present value if its insight was unlocked, the enterprise invested massive capital in the retention of extensive repositories. Systems like Hadoop addressed these scaling needs; however with the lack of data governance, schema, and overall structure, data lakes were plagued with poor performance and data quality issues. With the accelerating interest in new machine learning and AI applications, these limitations of data lakes frequently caused them to be viewed as data swamps.
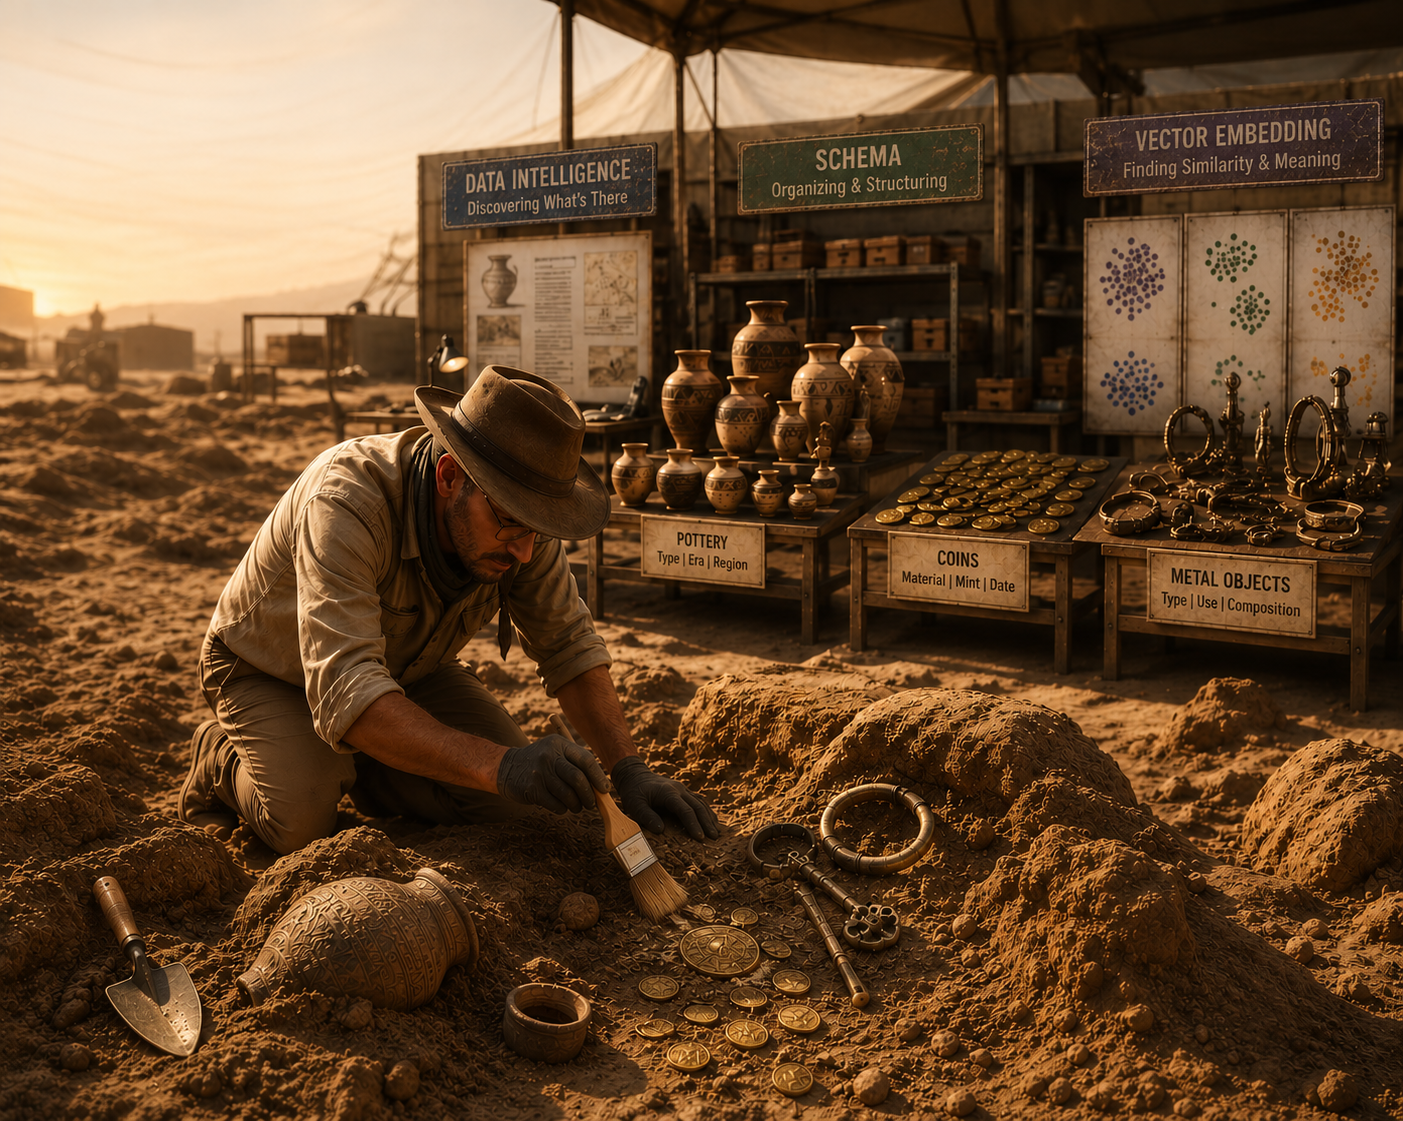
The 2020’s have seen these different evolutionary tales converge. Just as the data warehouse introduced schema for multiple systems to accelerate on-demand reporting, Data Lakehouse’s deliver consolidated intelligence, governance and metadata to provide structure to the chaos of data lakes. This process of deciphering meaning from raw data, categorizing it, and defining its importance, called data engineering, is highly similar to the science of archeology. The primary goal is not just to have the have the artifact, but to understand its purpose and importance.
Not unlike archeologists, data scientists are tasked with the monumental requirement of this understanding of data. What it is, its context, how it should be classified, valued, and measured. In fact, the process of data preparation currently takes up to 80-90% of a data scientist’s time. With the more staggering statistic that 50% of AI projects fail due to data preparation alone, the stakes are dire.
HPE’s Alletra Storage MP X10000 was introduced to the market in 2025 with the specific purpose of not being just another unstructured storage appliance. It promised a transformed experience for hot, next-generation workloads, with a cloud-like delivery experience through the HPE GreenLake Platform, and exa-scale expansion through its disaggregated, shared-everything architecture. A marquee capability defining this “next-generation” standard is the X10000’s Data Intelligence feature, and with its soon to be released expansion of capabilities, sets a new bar in the measurement of modern data appliances.
Data intelligence decodes and presents the hidden value of information. Providing lightning-fast answers to questions concerning what the data means, its purpose, and how it can be leveraged. It’s like the difference between having a library of books, and an online search functionality when you need rapid access to critical information. An online search tool exponentially helps you narrow down your efforts to a focused set of text. Now imagine the complexity of modern AI. We want to be able to search, create, and capture insight based on context, emotion, and themes across vast amounts of raw and unstructured data of different file types. Not just text, but audio, images, video, and beyond.
Essentially, the X10000 performs the procedures of data intelligence as an automated function of simply saving data to the appliance. What previously taxed multiple layers of an AI infrastructure and required data to be moved to separate locations to access these data intelligence services, is now a function of storing data.
The primary objectives of the X10000’s data intelligence are:
- Reduce time to insight
- Reduce data movement and load on the AI farm and GPUs
- Simplify intelligence in both coding and touch points
- Deliver functional, instant multi-modal RAG

In order to understand how the X10000 is enabling data intelligence, let’s first review the basics of the technology. Retrieval Augmented Generation (RAG) is an AI technique that enhances LLMs by infusing the features of unique and personal pieces of data into its responses. This provides numerous benefits, including removing the need to train an existing model. The AI will substitute or upgrade its output based on data artifacts supplied. This also reduces hallucinations and allows developers to keep AI applications up to date with the most current information without the need to continuously update models. This is delivered by two primary means; metadata extraction, and vector embeddings.
Metadata, or data about the data, is stored on the X10000 in Iceberg tables as well as optionally in output buckets to enable input into a vector database. With the assistance of LLM querying, the metadata provides the ability to search data based on its contents rather than simply the tags manually created on it by its owners. This becomes extremely valuable when you want to be able to identify the content of images, video, and audio files on demand. Iceberg tables provide a scalable rapid lookup location for the intelligence derived from the data. Users can then search and be instantly connected with data based on its hidden content immediately upon its upload to the platform.
Vector embeddings are numerical values assigned to data and stored within a database. The intent is that the numbers represent the semantic value of the data, and by grouping these vectors together, identify intersectionality of the information. This allows data that is similar to be quickly retrieved together, but more importantly, allows data to be found by its meaning. These numbers have multiple dimensions allowing individual data artifacts to have hundreds or potentially thousands of measurements which are then categorized with distance math. When compared together, these numbers begin to show patterns and similarity in the data, even when it does not have the same content, such as matching text.
At launch the X10000’s Data Intelligence feature delivered insights for text-based data. With the upcoming release of the X10000 OS, HPE has introduced data intelligence for audio, image, and video data with embedded NVIDIA NVAIE libraries. This has accelerated the deployment of enterprise class models with the expected optimizations, outcomes, and security that NVAIE provides, which will certainly expedite the ability for customers to move new pipelines into production AI workloads faster.
While the concept of data intelligence is not new, the automation of it to a point where deep subject matter expertise is not required to code and unearth the secrets of relics however certainly is. This advancement in the HPE Alletra Storage MP X10000 democratizes this analytic decoding to enable intelligence previously labored over, to be in the hands of AI enthusiasts drastically faster and simpler than ever before.